Compare · AI review writers
Writing from a prompt versus reading the record
A general AI assistant writes from what the leader remembers to type. Nextdot drafts from twelve months of work, in your framework.
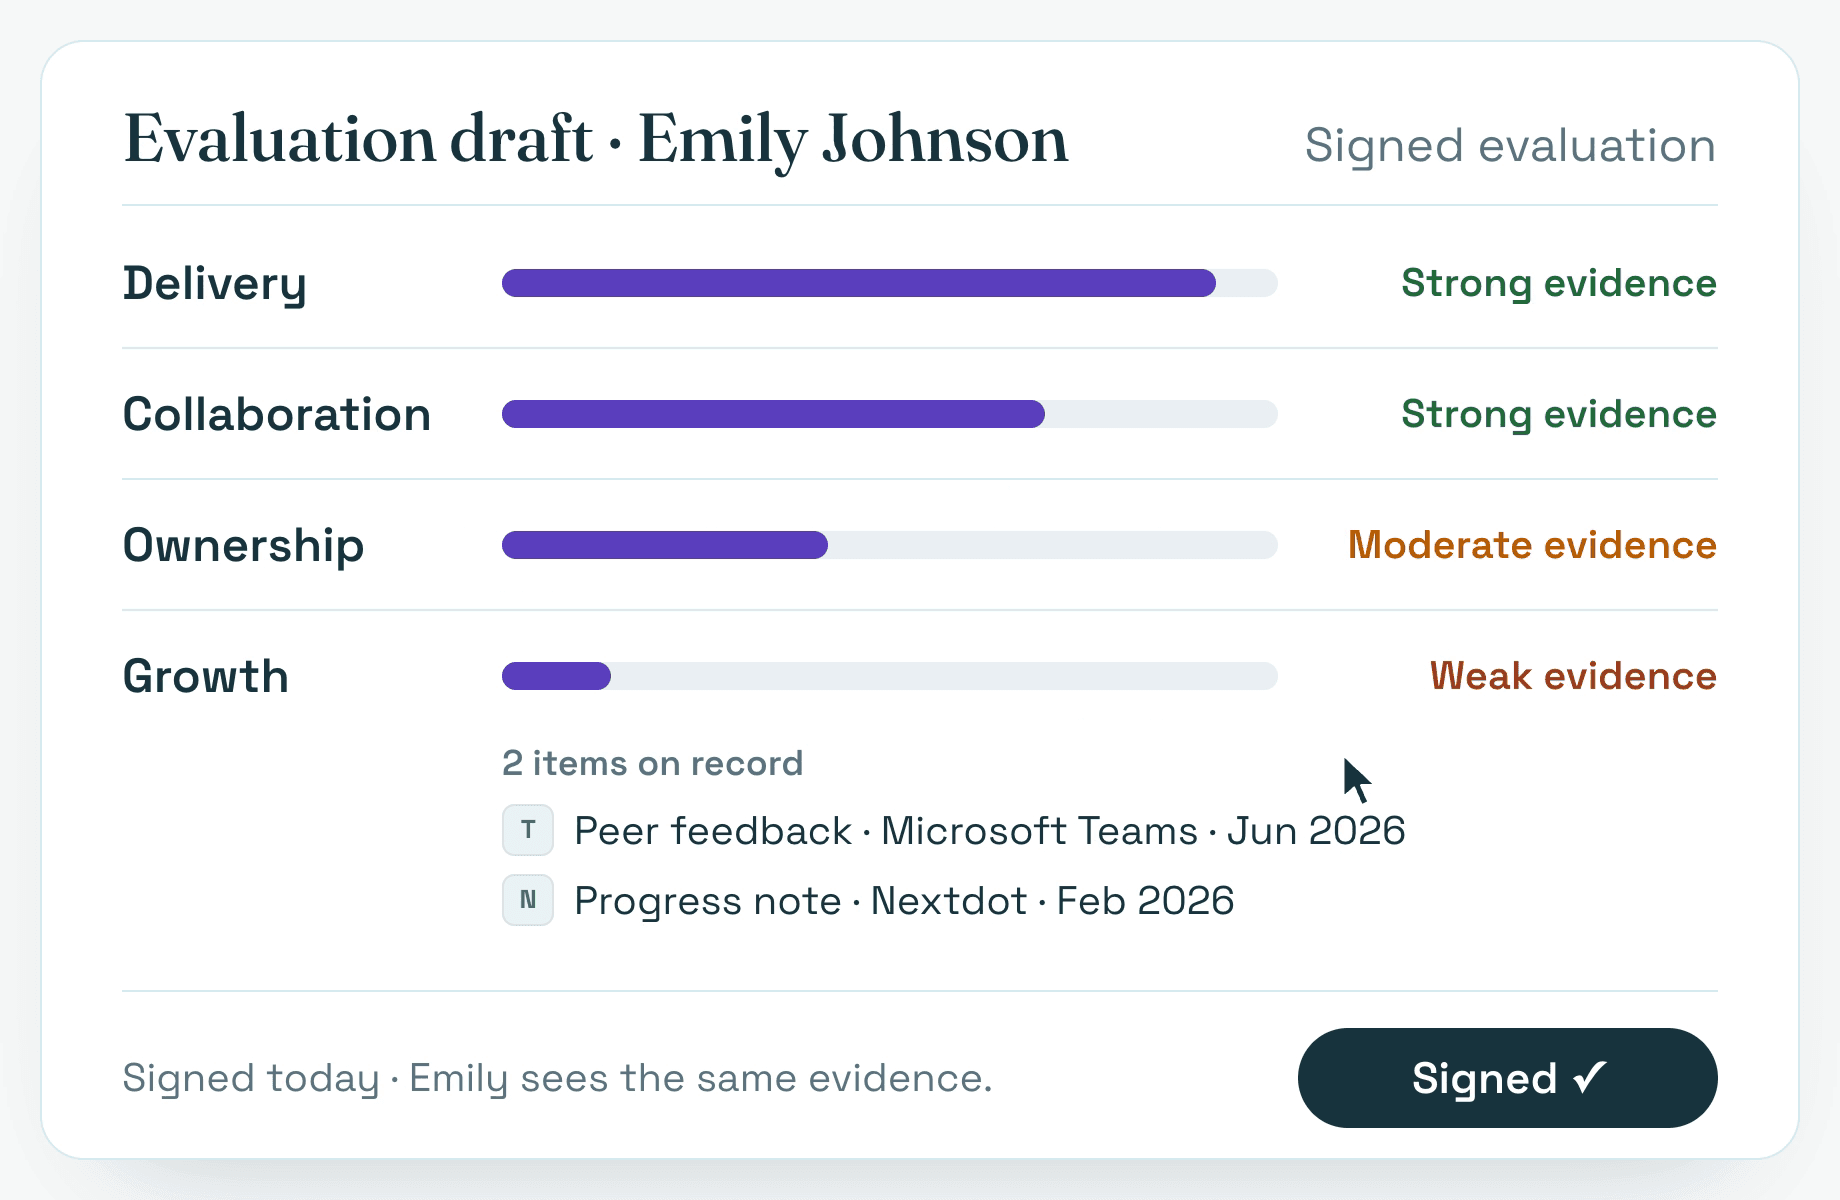
Three differences
Reads the record
The draft is built from the work people kept, not from a prompt.
Shows its evidence
Every dimension shows how much evidence stands behind it.
People decide
The leader reads the draft and writes their own evaluation; nothing is final until signed.
Why switch: Side by side
- Where evidence comes from
- NextdotThe record of work in the tools teams already use
- AI review writersWhat the leader types into the prompt
- When feedback happens
- NextdotWhile the work happens
- AI review writersNot part of the tool
- Who writes the first draft
- NextdotAI, per dimension, from the evidence
- AI review writersAI, from the leader's prompt
- Evidence behind each rating
- NextdotShown per dimension, down to the record
- AI review writersWhatever the prompt contained
- How much of the year is covered
- NextdotTwelve months from the first import
- AI review writersWhat the leader remembers to include
- What the person gets
- NextdotA view of their development all year
- AI review writersThe written review
- Developing others
- NextdotMeasured and visible to leadership
- AI review writersNot measured
- Who decides
- NextdotA leader writes and signs
- AI review writersA leader
FAQ: Questions, answered
More in the FAQ.
Isn't this just AI writing reviews?
No. AI drafts from the record of work, per dimension of your framework, and shows the evidence. The leader writes and signs the evaluation.
Is our data used to train models?
No. No model is trained on customer data.
Where to next
- FeaturePerformance evaluationAn evaluation drafted from the evidence and decided by a leader.
- FeatureAI in NextdotWhere AI works, what it reads, and where people decide.
- FeatureDotsEvery piece of evidence is a piece of work worth talking about.
- Use caseRun this year's review cycleRun the cycle that is about to start on twelve months of real evidence.
The best way to see it is on your own data
Happy to show it running on one team's tools — twelve months of work, your framework, your people.